Python 3.11+
The examples use the standard Python syntax and containers supported by the browser Judge; the Multi-source BFS invariant is independent of a minor Python release.
Verify in Python docs(opens in a new tab)Seed a BFS with every starting state to model simultaneous shortest-time propagation. Learn its decision rule, maintained state, Python cost model, and transfer from a focused drill to a full Interview Problem.
Recognize it when
Consider Multi-source BFS when the prompt's constraints and required operations match this shape: Seed a BFS with every starting state to model simultaneous shortest-time propagation.
Sign in to save your code and progress across devices. The lesson and problem statement remain public.
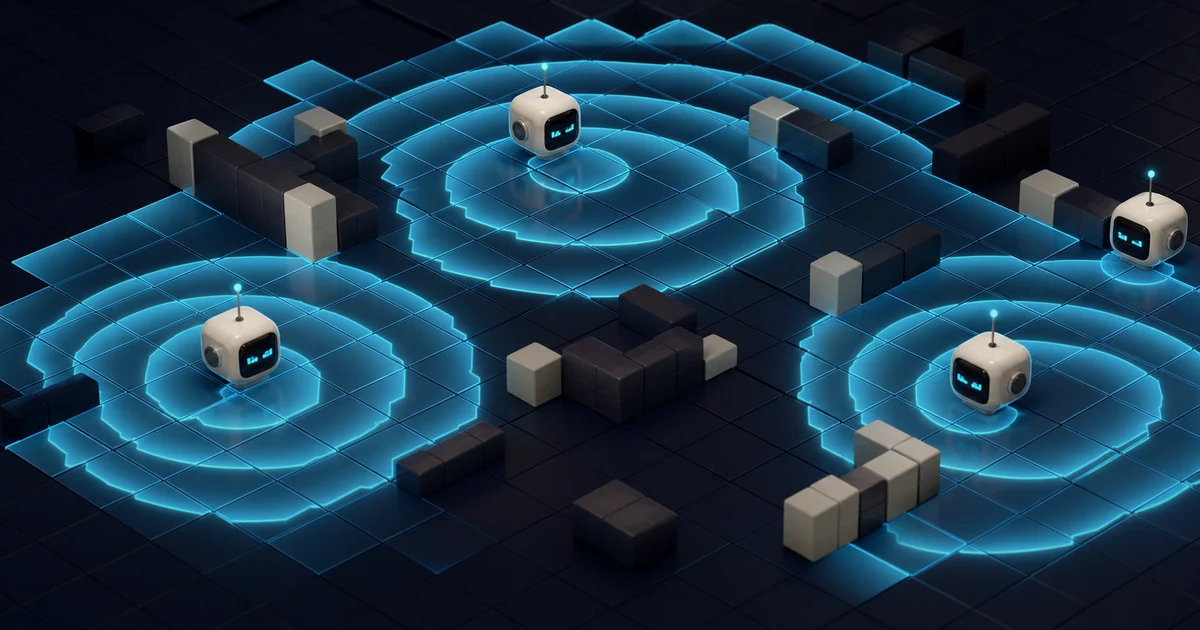
Multi-source BFS puts all starting states into one initial queue and assigns each distance zero. This is equivalent to adding a virtual super-source with zero-cost edges.
All sources compete in the same layer order. The queue therefore expands states by minimum distance to any source, not by distance to whichever source happens to be processed first.
from collections import deque

def multi_source_layers(adjacency,sources):
    queue=deque(); seen=set()
    for source in sources:
        if source not in seen: seen.add(source); queue.append(source)
    layers=[]
    while queue:
        layer=[]
        for _ in range(len(queue)):
            node=queue.popleft(); layer.append(node)
            for neighbor in adjacency[node]:
                if neighbor not in seen: seen.add(neighbor); queue.append(neighbor)
        layers.append(layer)
return layersImplement multi_source_layers(adjacency,sources). Return nodes grouped by nearest-source distance, preserving source then neighbor order.
Loading interactive editor.If it does not appear, the reference and starter code remain readable.Reload editor
Mark or assign distance when enqueueing. First discovery is optimal in an unweighted graph, and preventing later enqueues avoids duplicate work across source frontiers.
from collections import deque

def nearest_source_distances(adjacency,sources):
    distance=[-1]*len(adjacency); queue=deque()
    for source in sources:
        if distance[source]==-1: distance[source]=0; queue.append(source)
    while queue:
        node=queue.popleft()
        for neighbor in adjacency[node]:
            if distance[neighbor]==-1: distance[neighbor]=distance[node]+1; queue.append(neighbor)
return distanceImplement nearest_source_distances(adjacency,sources). Return shortest distance to any source, or -1.
Loading interactive editor.If it does not appear, the reference and starter code remain readable.Reload editor
Use one multi-source BFS for nearest-source distance from many origins in O(V + E). Repeating BFS from each source multiplies traversal cost. Weighted edges require Dijkstra with all sources initially at distance zero.
Say: “All sources form layer zero, so each later layer is one edge farther from its nearest source. I assign on first discovery.” Clarify duplicate sources, unreachable states, and whether the graph is unweighted.
Python 3.11+
The examples use the standard Python syntax and containers supported by the browser Judge; the Multi-source BFS invariant is independent of a minor Python release.
Verify in Python docs(opens in a new tab)Interview bounds depend on the stated representation, input model, and real Python operations.
| Operation | Average | Worst | Interview note |
|---|---|---|---|
| Multi-source BFS decision loop | O(rows * columns) | O(rows * columns) | When distance is measured to the nearest of many starts, enqueue all starts at distance zero before expanding one shared BFS. Every queued cell already has its minimum distance, because frontiers leave the queue in nondecreasing distance order. |
O(rows * columns) for the focused Expand a Multi-Source Frontier implementation.
These are the mistakes most likely to survive a happy-path example and fail a boundary case.
Applying the pattern without proving its ordering, monotonicity, or window invariant can silently miss valid candidates.
Prevent it: Write the decision rule beside the loop and verify it against Expand a Multi-Source Frontier before optimizing.
Avoid
def multi_source_distances(rows, columns, sources, blocked):
    pass
Use instead
from collections import deque

def multi_source_distances(rows, columns, sources, blocked):
    distances = [[-1] * columns for _ in range(rows)]
    blocked_cells = {tuple(cell) for cell in blocked}
    queue = deque()
    for row, column in sources:
        if (row, column) not in blocked_cells and distances[row][column] == -1:
            distances[row][column] = 0
            queue.append((row, column))
    while queue:
        row, column = queue.popleft()
        for dr, dc in ((1, 0), (-1, 0), (0, 1), (0, -1)):
            nr, nc = row + dr, column + dc
            if 0 <= nr < rows and 0 <= nc < columns and (nr, nc) not in blocked_cells and distances[nr][nc] == -1:
                distances[nr][nc] = distances[row][column] + 1
                queue.append((nr, nc))
    return distances
Where you will hit this: Expand a Multi-Source Frontier(opens in a new tab)
Starts from only the first source and ignores both additional sources and blocked cells.
Prevent it: Use the public tests and preserve this state: The queue is ordered by nondecreasing distance.
Avoid
from collections import deque

def multi_source_distances(rows, columns, sources, blocked):
    distances = [[-1] * columns for _ in range(rows)]
    if not sources: return distances
    queue = deque([tuple(sources[0])])
    distances[sources[0][0]][sources[0][1]] = 0
    while queue:
        row, column = queue.popleft()
        for dr, dc in ((1, 0), (-1, 0), (0, 1), (0, -1)):
            nr, nc = row + dr, column + dc
            if 0 <= nr < rows and 0 <= nc < columns and distances[nr][nc] == -1:
                distances[nr][nc] = distances[row][column] + 1; queue.append((nr, nc))
    return distances
Use instead
from collections import deque

def multi_source_distances(rows, columns, sources, blocked):
    distances = [[-1] * columns for _ in range(rows)]
    blocked_cells = {tuple(cell) for cell in blocked}
    queue = deque()
    for row, column in sources:
        if (row, column) not in blocked_cells and distances[row][column] == -1:
            distances[row][column] = 0
            queue.append((row, column))
    while queue:
        row, column = queue.popleft()
        for dr, dc in ((1, 0), (-1, 0), (0, 1), (0, -1)):
            nr, nc = row + dr, column + dc
            if 0 <= nr < rows and 0 <= nc < columns and (nr, nc) not in blocked_cells and distances[nr][nc] == -1:
                distances[nr][nc] = distances[row][column] + 1
                queue.append((nr, nc))
    return distances
Where you will hit this: Expand a Multi-Source Frontier(opens in a new tab)
Python slicing, copying, membership in lists, or repeated sorting inside the loop can invalidate the intended complexity.
Prevent it: Count every slice, copy, sort, membership check, and container update before claiming O(rows * columns).
Avoid
from collections import deque

def multi_source_distances(rows, columns, sources, blocked):
    distances = [[-1] * columns for _ in range(rows)]
    if not sources: return distances
    queue = deque([tuple(sources[0])])
    distances[sources[0][0]][sources[0][1]] = 0
    while queue:
        row, column = queue.popleft()
        for dr, dc in ((1, 0), (-1, 0), (0, 1), (0, -1)):
            nr, nc = row + dr, column + dc
            if 0 <= nr < rows and 0 <= nc < columns and distances[nr][nc] == -1:
                distances[nr][nc] = distances[row][column] + 1; queue.append((nr, nc))
    return distances
Use instead
from collections import deque

def multi_source_distances(rows, columns, sources, blocked):
    distances = [[-1] * columns for _ in range(rows)]
    blocked_cells = {tuple(cell) for cell in blocked}
    queue = deque()
    for row, column in sources:
        if (row, column) not in blocked_cells and distances[row][column] == -1:
            distances[row][column] = 0
            queue.append((row, column))
    while queue:
        row, column = queue.popleft()
        for dr, dc in ((1, 0), (-1, 0), (0, 1), (0, -1)):
            nr, nc = row + dr, column + dc
            if 0 <= nr < rows and 0 <= nc < columns and (nr, nc) not in blocked_cells and distances[nr][nc] == -1:
                distances[nr][nc] = distances[row][column] + 1
                queue.append((nr, nc))
    return distances
Where you will hit this: Rotting Oranges(opens in a new tab)
Official Python documentation supports language behavior. Canonical problem pages provide additional practice context.
python-docs · checked 2026-07-12
python-docs · checked 2026-07-27